What a “Free” VOD Service Taught Me About Modern Streaming Architecture
I was asked over the weekend by a friend to help him archive some weird movie from a “free” VOD service. Free, as in: you don’t pay from your bank account, but you do get thoroughly acquainted with the advertising department.
What started as a simple “where is the actual video?” turned into a surprisingly deep look at how a modern ad-supported VOD platform is put together.
I’ve deliberately anonymized the service, domains, and identifying details here. The interesting part is the architecture, not naming and shaming a particular operator.
The SPA (Single Page Application)
The VOD service in question is using a single-page application. SPAs tend to hide their API surface behind a build step, which means the source you get from “view source” is rarely the code that actually runs.
The URL I started with looked roughly like:
https://[service].tv/category/100001/weird-80ies-horror-collectionThe rendered page was simple enough: a hero image, a title, and a play button for each movie in the collection. There was no obvious API documentation and no useful video URL in the HTML. I also noticed something interesting when I tried the same content from a different country using a VPN.
I got a “not available in your region” message before the video itself had even been requested. So I opened DevTools and watched the network tab.
Multi-tenant by a single query parameter
The first interesting discovery was that the backend serving the application also served several other brands.
Different names. Different visual identities. Different catalogs.
But underneath, they were using the same API infrastructure.
The main differentiator was a siteId query parameter.
That explained a few things:
siteIdappeared throughout the API requests.- Different values produced different catalog responses.
- Some site IDs represented linear FAST channels.
- Others represented on-demand catalogs.
- The same general authentication/token mechanism appeared across them.
This is a familiar SaaS pattern: one platform, multiple tenants.
What’s interesting here is that the tenants aren’t corporate customers. They’re consumer-facing streaming brands. That makes the architecture efficient, but it also means tenant isolation becomes particularly important. If multiple brands share the same API and backend services, mistakes in isolation can potentially have a wider blast radius.
I confirmed the multi-tenant behaviour simply by changing the siteId in requests I was already observing. The API returned valid catalogs belonging to other brands.
No credentials were involved.
The namespace trick
The next layer was the catalog itself.
Every object in the API, show, movie, episode, category, playlist and so on has an identifier. These identifiers weren’t particularly meaningful to a human, but they weren’t completely random either.
By collecting IDs and grouping them by prefix, I could fingerprint parts of the catalog model.
For example, I encountered patterns along the lines of:
| Prefix | Apparent content type | Scope |
|---|---|---|
100000001xxxxxx | Travel / long-form | Brand-specific |
200000000xxxxxx | Categories / playlists | Shared |
200000010xxxxxx | On-demand video | Brand-specific |
The important point isn’t the exact numbers — those are anonymized here — but the fact that the identifier space itself carried information about the underlying data model.
The brand I was investigating used one particular namespace for its on-demand catalog. This isn’t a vulnerability by itself. A database key being predictable doesn’t magically grant access to anything. But it is useful for reconnaissance. Once you understand the namespace, you can make educated queries against the public API rather than treating every object as an isolated mystery.
The category URL off-by-one
Then I found a slightly odd piece of the catalog model.
The category URL contained one ID:
/category/100001/weird-80ies-horror-collectionBut the API endpoint that actually returned the episodes used a different ID. In the original system the relationship was effectively:
category ID
    ↓
playlist ID
    ↓
episodes
The two IDs differed by one.
Why?
Probably because the URL represented the marketing-facing category while the API was resolving that into another object representing the actual collection. That is an implementation detail rather than a security issue.
The practical workflow became:
- Fetch the category metadata.
- Resolve the corresponding playlist.
- Fetch the episodes.
- Fetch the episode metadata.
- Follow the stream URL.
It also illustrated something broader about these systems. The frontend isn’t necessarily talking to one clean “content API”. It’s stitching together several parts of an underlying CMS/data model.
The geo-block that wasn’t really a backend restriction
The application had regional restrictions as you see a lot in the VOD space. The SPA knew my country and used that information to decide whether certain content should be displayed.
The relevant logic was effectively along the lines of:
var countryCode = "XX";

if (countryCode !== "US") {
    // hide content
}
The exact implementation is more complicated than that, but the important point is where the decision was made.
The browser.
When I examined the API request itself, the backend returned the content metadata without enforcing the same restriction. In other words, the application had a client-side presentation rule that wasn’t obviously backed by an equivalent server-side authorization rule.
That’s an important distinction. A client-side restriction can control what the normal user interface shows. It cannot and should not be treated as a security boundary. The browser is observable and modifiable. Anyone inspecting the application can see the request being made and reproduce it independently of the UI.
If geographic licensing is a real security or licensing requirement, the enforcement point needs to be somewhere the client cannot simply override, for example, at the content-delivery or authorization layer.
The DRM layer
I won’t go deeply into this part because the interesting details aren’t necessary for the architecture story. And the setup is pretty standard for most VOD services.
There are effectively two classes of video.
Non-DRM content used ordinary HLS delivery. DRM-protected content followed a more conventional DRM workflow involving DASH, PSSH information and a separate license service.
The important observation was simply that the platform was not using one universal streaming mechanism. It was selecting a delivery architecture based on the content.
For the non-DRM material, the HLS manifest was directly accessible.
And that led to the next rabbit hole.
Following the video all the way to the CDN
Once I had the episode metadata, I had an HLS URL. At that point I could have stopped.
Instead I wondered: What is actually sitting behind that HLS URL?
The API returned something conceptually like:
video_hls_url
    ↓
https://[cdn]/files/[namespace]/vi/[shard]/[shard]/[id]/s[id].m3u8
The HLS master playlist contained two variants:
5 Mbps  → hi
2 Mbps  → lo
The variant playlists then referenced ordinary MPEG-TS segments. So far, nothing exotic.
But the same API response also contained another field:
video_urlAnd that pointed directly to an MP4.
For one example, the relationship looked like:
HLS:
.../vi/f3/95/10682226/s10682226.m3u8

MP4:
.../vi/f3/95/159c12162ccc1dcea41528198b4c4aff.mp4
A HEAD request to the MP4 returned:
HTTP/2 200
content-type: video/mp4
content-length: 1645900340
accept-ranges: bytes
So the “video URL” wasn’t just an old metadata field. It was a live CDN object.
And that changed the architecture diagram considerably:
                  ┌── HLS master
                  │
API → episode ────┼── HLS variants → TS segments
                  │
                  └── MP4 object
The application API was effectively handing out references to both the streaming representation and the underlying media object.
Then I found the object storage
The CDN itself provided another clue. A separate CDN-facing endpoint returned an S3-style object listing.
The response contained familiar object-storage fields such as:
<ListBucketResult>
<Name>...</Name>
<IsTruncated>true</IsTruncated>
...
The HTTP response headers identified an S3-compatible object-storage provider as the backend. Trying to enumerate the underlying object-storage bucket directly didn’t produce the same result; the bucket listing required authorization.
But the CDN-facing endpoint exposed a public listing response. So I was looking at a CDN layer exposing an object-store-backed namespace. And the public listing contained far more than just videos.
The transfer manifest
One of the objects in the listing looked like a transfer-job manifest. Which after some looking into turned out to be a binary-framed record stream containing entries such as:
directory_header:
{
    path: "/mnt/hcs/xxxxxx/content/files/"
    num_entries: 1337
}

file_info:
{
    path: ".../files/..."
    last_modified_time: ...
    size: ...
}
the manifest contained references to the underlying filesystem layout used during content ingestion. There are directories for images, video, subtitles and other content.
At this point the investigation had moved several layers below the web application.
application metadata
        ↓
CDN paths
        ↓
object storage
        ↓
content ingestion
The storage naming convention
The video objects followed a remarkably consistent structure.
For example:
/vi/f3/95/10682226/s10682226.m3u8
/vi/f3/95/159c12162ccc1dcea41528198b4c4acd.mp4
Another episode:
/vi/53/7d/10682227/s10682227.m3u8
/vi/53/7d/ebf4ffbf7625ed3c051a3b2083590eff.mp4
And another:
/vi/c8/31/10682228/s10682228.m3u8
/vi/c8/31/28fa9018a5ee3a30a6754d546457ffs.mp4
The pattern was clearly systematic:
/files/
    [content namespace]/
        vi/
            [two-character shard]/
            [two-character shard]/
                [node ID]/
                    HLS files

                [32-character object ID].mp4
The same general scheme appeared elsewhere in the content tree.
Subtitles had their own paths. Images had their own paths. Different asset types used the same broad storage philosophy.
Was the 32-character ID a file hash?
Naturally, I wondered whether the 32-character filename was simply an MD5 checksum of the MP4.
It looked exactly like one. So I downloaded one of the relatively small videos and checked.
The result:
Object:
3ede1cd758e9f2c75773b754143df1ff.mp4

MD5(actual file):
10c8f968f050c3e40d08a32a549559ba
Not a match.
I repeated the experiment with another object.
Again, no match.
I also tested several obvious relationships:
- MD5 of the node ID
- MD5 of the API object ID
- MD5 of the public URL
- MD5 of the 32-character filename
- SHA-1
- SHA-256
- filename plus extension
None reproduced the storage shard. So the responsible conclusion isn’t “I cracked the hashing algorithm.”
It’s the opposite.
The 32-character media identifier appears to be an opaque application/storage identifier, while the two-character directory shards are generated by some other part of the ingestion/storage pipeline.
The older namespace told a different story
The newer media namespace seemed deliberately opaque.
While I was looking around the catalog, I noticed a separate set of older objects sitting under a different content namespace. Those objects followed a noticeably more predictable storage layout.
For a small sample of those objects, the directory shards used in the storage path were reproducible from publicly visible identifiers. The relationship held across every sample I tested.
I’m leaving the exact derivation out of this write-up.
The point isn’t the specific transformation. The point is that the platform appears to have moved from a predictable storage scheme, where paths could be derived from public identifiers, to an opaque one, where they can’t.
That’s the right direction for a content platform to take. Predictable storage paths make bulk enumeration easier than it should be. Opaque ones don’t, even when everything else about the system is observable.
The architecture that emerged
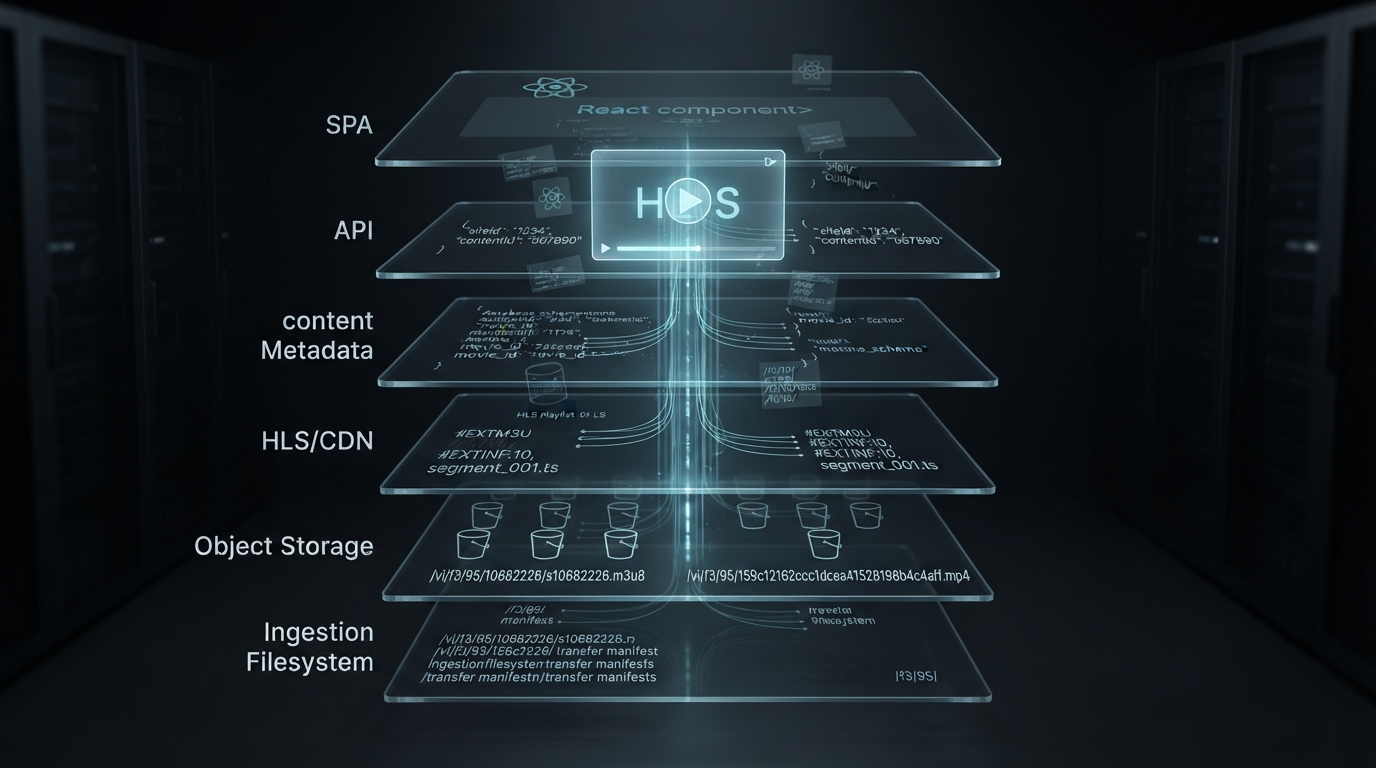
After following the references down through the system, the architecture looked roughly like this:
                     WEB APPLICATION
                           │
                           ▼
                     PUBLIC API
                           │
              ┌────────────┴────────────┐
              │                         │
          siteId                    node/content ID
              │                         │
              ▼                         ▼
       tenant/catalog             episode metadata
                                        │
                              ┌─────────┴─────────┐
                              │                   │
                              ▼                   ▼
                         HLS manifest          MP4 object
                              │                   │
                              ▼                   ▼
                          Content CDN        Content CDN
                              │                   │
                              └─────────┬─────────┘
                                        ▼
                                  Object storage
                                        │
                                        ▼
                               ingestion filesystem
                                        │
                                        ▼
                               transfer manifests
What this says about FAST/VOD platforms
Free ad-supported streaming has an unusual engineering balance.
The economics encourage:
- shared infrastructure
- reusable CMS platforms
- automated ingestion
- CDN-backed object storage
- relatively small operations teams
- fast deployment across multiple consumer brands
At the same time, the technology stack is not simple.
You’re dealing with:
- multi-tenancy
- regional licensing
- content metadata
- multiple delivery formats
- DRM
- HLS
- CDN caching
- object storage
- automated transcoding
- ad insertion
- content ingestion pipelines
The result is a system where a surprisingly large amount of architecture can become visible through ordinary application behaviour.
In this case I found several examples:
- client-side geographic restrictions that weren’t obviously enforced at the API layer
- multiple consumer brands sharing a common backend
- catalog identifiers that exposed useful information about the underlying schema
- a category/playlist model requiring an extra resolution step
- public CDN URLs that exposed both HLS and MP4 representations
- an S3-compatible storage layer behind the CDN
- transfer manifests exposing the underlying content filesystem structure
None of those observations, individually, tells the whole story.
Together, they reveal quite a lot about how the platform is constructed.
Methodology and scope
Everything in this post is OSINT. I observed a publicly accessible application and reasoned about what its behaviour tells me.
I used browser DevTools, ordinary HTTP requests, and curl to inspect requests the application itself was already making.
No authentication credentials belonging to anyone else were used. No DRM keys were extracted. No authentication mechanism was bypassed. No attempt was made to compromise the underlying storage service.
I deliberately stopped at understanding the architecture rather than attempting broad enumeration or bulk acquisition of content. Some observations in this post are described at a level of generality that stops short of the full derivation, including the storage-namespace discussion above. The point of the piece is the engineering, not the operational detail.
The service, domains, CDN, storage backend and identifying URLs have all been anonymized. The interesting part is the architecture, not naming and shaming a particular operator.